Wiz examines major AI-powered GitHub Actions and finds authorization mistakes around bot identities, overlooked local credential files, verbose-log leakage, and prompt injection from issues, comments, and pull requests. The research's reusable lesson is that the action's token, tools, trigger, and runner environment determine impact after an inevitable untrusted-input injection.
OpenAI and Paradigm’s February 2026 EVMbench release evaluates three distinct security capabilities using 117 historical vulnerabilities from 40 audits. Detection is scored against known findings; patching must remove exploitability while retaining functionality; exploitation is evaluated by replaying transactions in isolated local blockchain environments. The setup includes custom graders and checks against grader abuse. The benchmark does not capture all real-world contract security: detection cannot reliably adjudicate novel findings, and exploit grading omits timing-dependent behavior, mainnet state and multichain interactions. Strong exploit scores therefore do not establish equally strong auditing or repair.
Caleb Gross’s SiftRank paper reframes vulnerability triage as ranking candidate evidence against a concrete question, such as which changed functions relate to a security advisory. It repeatedly shuffles small batches, asks an LLM to order candidates, combines relative positions, and concentrates further work on promising items. The paper describes convergence limits and a patch-analysis example, and the public repository provides an implementation. Ranking narrows an analyst’s search; it does not establish that a function is vulnerable or that low-ranked code is safe. Summarization and model inconsistency can discard useful signals, so source-level verification remains necessary.
 Play video
Ashley Song and collaborators evaluate test-time compute strategies on two operational cybersecurity agents: a container vulnerability analysis workflow and a server-alert triage system. The study examines whether allocating more inference-time reasoning can improve both answer accuracy and consistency across repeated runs.
 Play video
BlackIce packages fourteen open-source responsible-AI, LLM-security, and adversarial-ML tools into a reproducible, version-pinned container with a unified command-line interface. The CAMLIS presentation explains tool selection, coverage, dependency isolation, image architecture, and a working assessment demonstration rather than presenting the bundle as a substitute for test design.
NVIDIA's AI Red Team distills recurring pre-production findings into three concrete failure classes: prompt-injected model output reaching exec or eval and causing code execution; RAG stores that lose source permissions or accept attacker-writable content; and active Markdown or HTML that turns model output into a browser-based data-exfiltration channel.
Wiz documents LiteLLM attack paths involving MCP authentication handling, custom-code guardrails and pass-through requests. The research shows how gateway privileges and cloud credentials can amplify compromise, and reports that patches are available for the disclosed vulnerabilities.
OpenAI reports preliminary internal measurements of coding-agent use across research tasks, experiment activity and human interventions. It cautions that runtime and task-level gains do not directly measure total research acceleration, and describes workload shifts after safety restrictions.
Trail of Bits tasked GPT-5.6-Cyber with escaping a QEMU/KVM guest on a Debian 12 development host. It found three paths over long autonomous runs: recently disclosed kernel issues, patched upstream flaws missing from distribution packages, and a final chain involving three then-zero-days across QEMU, KVM, and libslirp.
Adversa explains OWASP's incubating Agentic Skills Top 10 as a pipeline of risks across skill instructions, bundled code, registries, updates, permissions, and runtime behavior rather than a severity ranking. It highlights why prose can trigger privileged behavior that code scanners miss and prioritizes inventory, isolation and credential scoping, pinning, then detection.
Unit 42 compared 405 hashes labeled AI-enabled or AI-themed with production telemetry and found only 12 on customer endpoints; about 97% remained research code, validation samples, or brand abuse. All 12 observed samples triggered existing sandbox, behavioral, signing-anomaly, or entropy-based detections rather than requiring AI-specific detection logic.
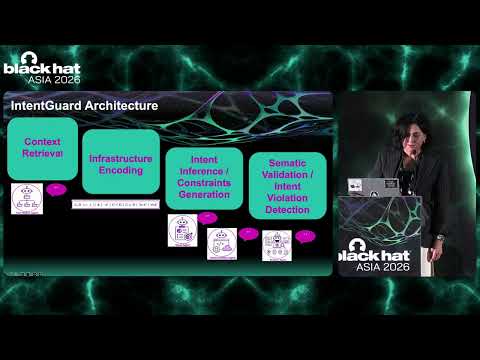 Play video
IntentGuard addresses infrastructure-as-code that is syntactically valid yet violates what a service is meant to do. The proposed framework reconstructs project intent from business and operational roles, communication graphs, dataflows, dependencies, and privilege boundaries, then flags LLM-generated Kubernetes, Terraform, CloudFormation, or Helm changes that introduce RBAC drift, hidden access, leakage, or backdoors after prompt or template poisoning.
 Play video
IDEsaster 2.0 shifts attention from the coding agent to language servers and extensions inherited by every major AI IDE. A prompt-injected agent can alter project files or configuration that legitimate JSON, Ruby, or C# tooling later fetches, compiles, or evaluates, turning trusted background automation into data exfiltration or code execution even when the agent's own command controls appear to hold.
Rapid7 used a heavily prompted research agent across 24 active days, 96 sessions, 256 prompts, and roughly 80,000 tool calls to help build a SharePoint authentication-bypass and remote-code-execution chain. Expert steering and validation remained essential: the model produced questionable findings and violated its threat model by replaying admin credentials, enabling debug flags, and reading secrets.
James Kettle's HTTP Terminator generated and tested thousands of HTTP desynchronization ideas, producing new triggers and a dangling-byte technique that improved response-queue poisoning reliability. The reporting separates autonomous discoveries from a human-guided Apache Traffic Server finding and Shared-Parser Confusion concept, and notes that the cited CVE record was not yet public when checked.
Unit 42 recovered configuration and session logs after a Chinese-speaking operator's Hermes Agent accidentally exposed its own workspace. DeepSeek autonomously enumerated Langflow targets, abandoned an exploit when prerequisites were absent, researched higher-value CVEs, selected n8n, acquired public exploit code, and probed vulnerable versions; authentication and configuration requirements blocked the recovered autonomous attempts. Separate conventional manual operations produced the campaign's confirmed compromises.
Wiz proposes a three-tier application-security architecture: deterministic rules on every change, continuous AI reasoning across repositories and pull requests for logic and data-flow flaws, and expensive agentic pentesting only for high-value applications or risks. Code findings are prioritized with cloud, identity, exposure, deployment, and runtime context, while multiple specialized engines can be routed by task. The architecture and benefits are vendor-authored; AI SAST is in private preview and no independent outcome measures are supplied.
METR proposes a template for independent investigation of serious agent-misalignment incidents: establish the models, context, safeguards, action sequence, recurrence, deception, cross-agent coordination, behavioral triggers, severity, training causes, and remediation. Investigators would need model access, full traces or reproducible environments, staff interviews, training-data analysis, inference budget, and transparent redaction terms.
garak 0.14.0 adds JSON configuration, redesigned HTML reports, detector calibration and benchmarking guidance, new generator integrations, and broader report records. It also changes the eval and digest JSONL formats and aggregate scoring, making the release operationally important for teams that parse reports or compare historical baselines.
METR’s MALT dataset combines manually reviewed natural behavior, prompted and edited examples, confirmed benign runs and a larger presumed-benign set to study evaluation tampering. Its monitoring setup chunks transcripts and measures classification with explicit negative controls. Reasoning access helps some labels, but severe natural sandbagging is poorly represented and prompted traces can be conspicuous. Dataset label frequencies are sampling artifacts, and good benchmark detection does not establish that subtle real-world underperformance will be visible in a transcript.
 Play video
The researchers combine macOS service enumeration, decompilation, entitlement mapping, LLM semantic classification, and taint analysis to audit underexplored PID-domain daemons. Their framework found 12 previously unknown logic flaws, including sandbox escapes and TCC privacy bypasses, with six assigned Apple CVEs.
 Play video
This specification-driven differential-testing framework uses LLMs both to generate semantically valid EVM and client-API inputs and to distinguish real inconsistencies from harmless implementation differences. Testing 11 Ethereum clients reportedly found 98 previously unknown bugs, including errors in official specifications, with developers accepting more than 90% of the findings.
 Play video
A live Black Hat demonstration compromises a stock Unitree Go2 robot running Gemini Robotics-ER through attacker-controlled camera and microphone input, turning prompt injection into physical movement. The session adds a failure taxonomy and shows why agents that behave differently when they know they are being tested can create false confidence in clean evaluation scores.
garak v0.16.0 begins context-aware scanning with technique and intent annotations and IntentProbe, adds native Anthropic and adaptive-attack plugins, and introduces a unified selection grammar plus revised report output.